Executive Summary and Impact
Developed as part of the Kuppam Net Zero Carbon roadmap in collaboration with AP Government and IIT Kanpur, this methodology decouples underlying structural growth from short-term environmental fluctuations. By combining STL decomposition with PACF lag features and 24-hour diurnal profile scaling, we forecast long-term grid demand and peak instantaneous load.
Core Thesis
A time-series model assumes, implicitly or explicitly, that the future has some structural relationship with the past. Long-term infrastructure planning becomes harder when the system itself is changing. Historical data can tell us how demand behaves, but it cannot by itself tell us what the future system will become.
Act I: The Fallacy of Historical Extrapolation
1. The Problem
Forecasting electricity demand sounds like a conventional time-series problem.
Given enough historical observations, we should be able to learn the trend, capture seasonality, and predict what comes next.
That framing worked reasonably well until we asked a different question:
Key Insight
How do you forecast electricity demand for a growing region when the demand you are trying to predict is itself being reshaped by population, industry, and planned interventions?
We were working on the Kuppam Net Zero Carbon roadmap, a joint initiative involving the Government of Andhra Pradesh and IIT Kanpur. The available data gave us several ways of looking at the electricity system:
- Monthly consumer billing data across multiple consumer categories
- Hourly load data from the higher-voltage network
- Solar generation data
- High-tension industrial loads
- Agricultural feeder information
- Weather and other contextual variables
The consumer billing dataset was particularly useful for the long-term problem. It provided a long historical record of monthly electricity consumption across the region, with separate consumer categories that could also be aggregated into a total demand series.
At first glance, this looked like a standard forecasting problem.
It wasn't.
2. The Problem With Learning the Future From the Past
A historical load series contains a lot of information.
It contains recurring seasonal behavior. It contains the effect of weather. It contains short-term persistence. It contains the gradual growth of electricity consumption over time.
But it also contains something more subtle:
System Constraint
It reflects the system that existed when the data was generated.
That distinction matters when the system is expected to change.
Kuppam's future electricity demand was not expected to simply continue along the historical trajectory. Population could change. Industrial activity could expand. New interventions could alter electricity consumption. Agricultural demand could evolve.
These changes are not necessarily visible in historical electricity consumption.
A model trained entirely on the past therefore faces an uncomfortable limitation:
It can learn how the existing system behaves, but it cannot automatically learn structural changes that have not happened yet.
This changed how we thought about the problem.
We stopped asking: "Which model gives us the best long-term forecast?"
and started asking: "Which parts of the future can the historical data actually teach us?"
That question led to the central design decision of the forecasting pipeline.
3. Separate What History Knows From What Planning Assumptions Know
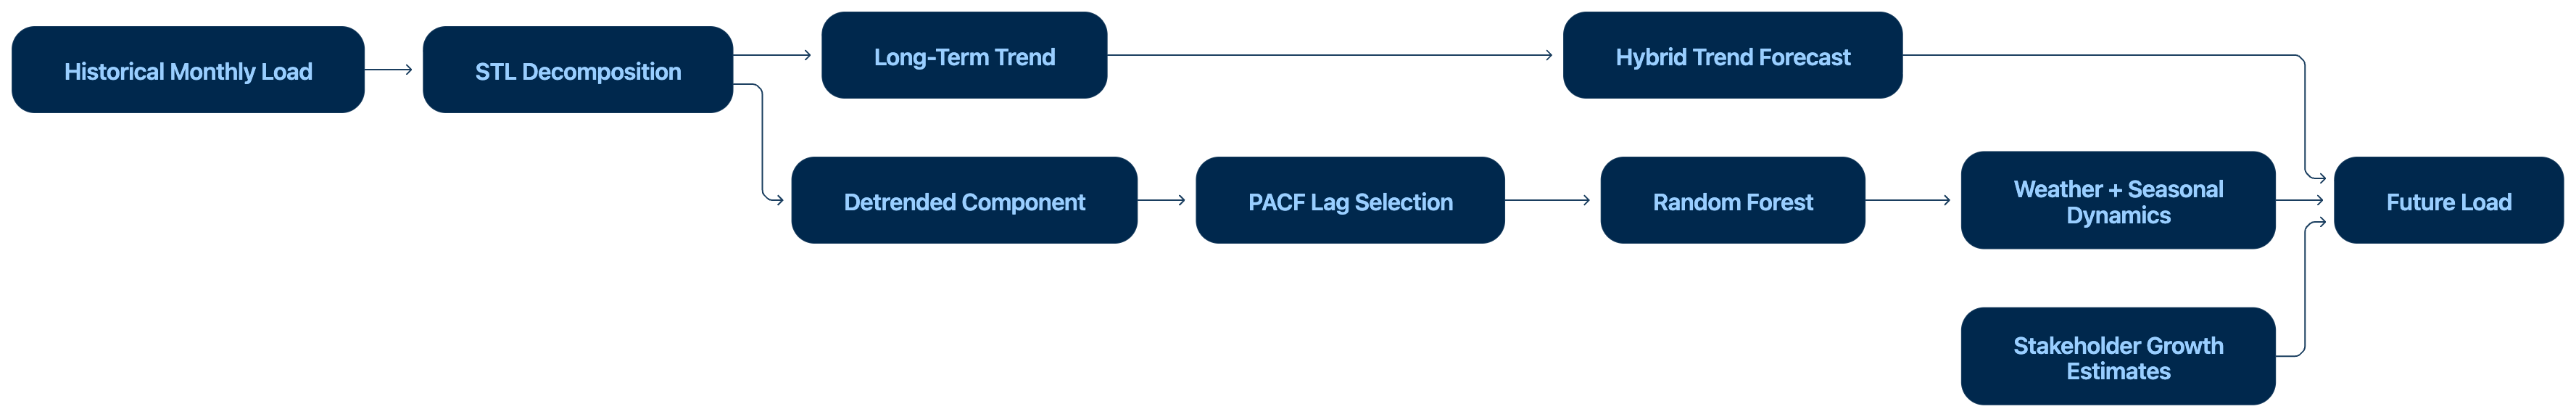
Our key methodological decision was to separate the long-term trend from the shorter-term fluctuations around it.
Instead of asking one machine-learning model to explain everything, we decomposed the historical series first.
The distinction was simple:
- The trend represented how the system was growing.
- The detrended component represented the shorter-term behavior around that trend.
That allowed us to use machine learning for the part where historical observations were informative, without pretending that the model could independently discover future structural growth.
Act II: STL Decomposition and Feature Engineering
4. Decomposing the Load Before Modeling It
We used STL decomposition with a 12-month period to split each monthly load series into:
Y(t) = Trend(t) + Seasonal(t) + Residual(t)
- Trend (T_t)
- Seasonal component (S_t)
- Residual component (R_t)
The objective was not merely to make the series "more stationary."
It was to give the model a narrower question to answer.
Instead of predicting: "What will total electricity consumption be years from now?"
the Random Forest was asked to learn: "Given recent load behavior and current environmental conditions, how does demand move around its underlying trend?"
 Model Output and Historical vs Forecasted Load Profiles
That is a much more constrained problem.
The long-term trend was handled separately using smoothing and a hybrid trend-forecasting approach. The original STL trend was smoothed using exponential moving averages, followed by STL and Holt linear trend forecasting through exponential smoothing. The resulting future trend was then reintegrated with the machine-learning forecast.
This separation became more important than the choice of any individual algorithm.
5. Giving the Model Memory
Once the long-term trend had been removed, the remaining series still had temporal structure.
Load today depends partly on what happened recently.
But simply throwing dozens of historical lags into a model creates another problem: most of those lags are not necessarily useful.
We therefore used the Partial Autocorrelation Function (PACF) to identify autoregressive lags.
Rather than selecting lags arbitrarily, we examined the partial autocorrelation structure over a longer lag window and selected the significant lags beyond the immediate annual cycle. These became additional autoregressive features for the Random Forest.
The resulting feature set combined two different types of information:
- Historical memory: Selected autoregressive load lags
- External conditions: Maximum temperature, Rainfall, Lagged rainfall, Sunshine hours, PCI, A rainfall-regime indicator
The rainfall indicator was itself engineered from lagged rainfall. It identified whether the previous month's rainfall was above its historical mean, giving the model a simple way to distinguish rainfall regimes rather than relying exclusively on a continuous rainfall value.
6. Why Random Forest Was a Practical Choice
Random Forest was not selected because it was the most sophisticated forecasting algorithm available.
It was selected because of the structure of the problem.
After decomposition, the machine-learning task was essentially a tabular regression problem.
Each observation combined:
- Weather variables
- Engineered weather indicators
- Selected historical lags
- The detrended electricity-demand target
The relationships between these variables did not need to be assumed to be linear.
For example, the effect of rainfall could depend on its recent history. Temperature effects could interact with the existing load regime. Lagged demand could matter differently under different environmental conditions.
A tree ensemble was a practical way to capture these interactions without imposing a particular functional form.
More importantly, the model was being used for a specific subproblem. We did not need it to understand the entire future electricity system. We needed it to model the short-term dynamics that remained after the long-term structure had been separated.
That distinction made the model choice much easier.
Act III: Exogenous Growth and Block Iteration
7. The Part a Time-Series Model Cannot Learn
This was the uncomfortable part.
Even after separating the trend, we still had to answer:
Key Insight
What happens when the future system grows faster or differently than the historical system?
There was no historical observation from which a model could directly learn a future industrial expansion or an influx of workers.
So we introduced growth adjustments based on planning estimates and discussions with stakeholders.
These assumptions reflected the expected structural evolution of the region, including planned interventions and potential inorganic growth associated with industrial activity and population changes.
The important design choice was not the particular growth assumption.
It was where we put it.
We did not hide the assumption inside the machine-learning model.
Instead:
- Historical data was used to estimate the existing trend.
- Machine learning modeled short-term deviations around that trend.
- Future growth assumptions were applied explicitly.
- The components were recombined into the final forecast.
This gave us something that was statistically less "pure" than asking a model to extrapolate history indefinitely. But it was considerably more useful for planning.
8. Forecasting in Blocks, Not One Giant Leap
There was another practical problem.
We were forecasting several years into the future.
A model that predicts one month ahead can use observed historical load values as its lag features. A model predicting years ahead cannot.
Eventually, its own predictions become part of the history used to generate subsequent predictions.
We performed the multi-step forecast recursively in 12-month blocks:
- Predictions were appended to the available series.
- Lag features were recomputed.
- The next forecast block used the updated series.
- Growth adjustments were incorporated into the future trajectory.
This is an important difference from simply fitting a model and asking it for a long sequence of predictions.
Act IV: Hourly Profile Reconstruction and Peak Load
9. Then We Realized We Had Solved Only Half the Problem
At this point, we had a monthly electricity-demand forecast.
But the planning question was not: "How many kilowatt-hours will the region consume this month?"
It was closer to: "What will the load actually look like when the grid experiences its peak?"
This distinction matters because infrastructure is constrained by instantaneous demand.
A monthly energy total can be identical for two very different load profiles.
The monthly forecast gave us the magnitude. We still needed the shape.
10. Turning Monthly Energy Into Hourly Load
This became the second half of the forecasting problem.
We had a limited period of high-frequency load data from the 220 kV network. Instead of attempting to train another complex model to predict every future hour, we asked a simpler question:
Key Insight
What does a typical day in each month look like?
We classified historical observations into weekday and weekend behavior, calculated daily averages, and identified representative peak and valley days.
For each month, we extracted 24-hour profiles representing:
- Weekdays
- Weekends
- Peak days
- Valley days
The crucial assumption was: The future month will broadly retain the hourly shape of its corresponding historical month, while its overall magnitude changes according to the long-term forecast.
11. Scaling the Shape, Not Relearning It
For each future month, we took the corresponding historical monthly profile and calculated a scaling factor:
L_future(t, h) = S_hist(h) × [ E_monthly(t) / E_hist_mean ]
Every hourly value in the representative profile was then multiplied by this factor:
Future Hourly Load = (Historical Hourly Shape) × (Future Monthly Magnitude)
This gives us an important separation:
- Monthly forecasting answers: How much electricity will the system consume?
- Profile reconstruction answers: How might that consumption be distributed across the hours of the day?
12. Changed Belief
Operator Takeaway
Initial belief: Forecasting electricity consumption is primarily a time-series modeling problem.
Changed belief: Long-term electricity forecasting is a decomposition and planning problem. We need to separate what historical data can explain from what future assumptions require us to specify, and we need to distinguish monthly energy magnitude from hourly peak-demand shape.
The most useful model was therefore not the one that made the fewest assumptions. It was the one that made its assumptions visible.